Alembic Autogenerate: What It Detects, What It Misses, How to Fix It
How Alembic autogenerate compares SQLAlchemy metadata with the live database, the changes it cannot see, constraint naming conventions and SQLite batch mode.
SQLAlchemy's migration tool: Python revision scripts with upgrade() and downgrade(). SchemaDrawer runs Alembic 1.17.1 on SQLAlchemy 2.0 against a throw-away database of the engine you choose and returns an SVG of the schema it produces.
Upload the revision scripts, that is the contents of your versions/ directory. SchemaDrawer supplies its own env.py and alembic.ini, pointed at the throw-away database, and runs the scripts in one transaction where the engine allows it.
The sample below is the PetClinic schema written for Alembic, one of the sets SchemaDrawer's own tests draw on every engine:
alembic/versions/
├── 0001_create_owners_and_pets.py
├── 0002_create_vets.py
└── 0003_create_visits.py
Python revision scripts that use alembic.op and SQLAlchemy.
alembic upgrade head. The database is a fresh PostgreSQL, MySQL, MariaDB, SQL Server, Oracle or SQLite container in the version you ask for; nothing of yours is touched.
PostgreSQL 10, 11, 12, 13, 14, 15, 16, 17, 18 MySQL 8.0, 8.4, 9 MariaDB 10.6, 11.4, 11.8, 12 SQL Server 2017, 2019, 2022, 2025 Oracle 21, 23 SQLite
migrationType=ALEMBICOwners, pets, types, vets, specialties and visits: the same seven tables every sample set on this site creates. These are the exact files the tests upload.
"""create owners and pets"""
from alembic import op
import sqlalchemy as sa

revision = '0001'
down_revision = None
branch_labels = None
depends_on = None


def upgrade():
    op.create_table(
        'owners',
        sa.Column('id', sa.Integer, primary_key=True, autoincrement=False),
        sa.Column('first_name', sa.String(50), nullable=False),
        sa.Column('last_name', sa.String(50), nullable=False),
        sa.Column('address', sa.String(255), nullable=True),
        sa.Column('city', sa.String(80), nullable=True),
        sa.Column('telephone', sa.String(20), nullable=True),
    )

    op.create_table(
        'types',
        sa.Column('id', sa.Integer, primary_key=True, autoincrement=False),
        sa.Column('name', sa.String(80), nullable=False),
    )

    op.create_table(
        'pets',
        sa.Column('id', sa.Integer, primary_key=True, autoincrement=False),
        sa.Column('name', sa.String(50), nullable=False),
        sa.Column('birth_date', sa.Date, nullable=True),
        sa.Column('type_id', sa.Integer, sa.ForeignKey('types.id'), nullable=False),
        sa.Column('owner_id', sa.Integer, sa.ForeignKey('owners.id'), nullable=False),
    )


def downgrade():
    op.drop_table('pets')
    op.drop_table('types')
    op.drop_table('owners')
"""create vets"""
from alembic import op
import sqlalchemy as sa

revision = '0002'
down_revision = '0001'
branch_labels = None
depends_on = None


def upgrade():
    op.create_table(
        'vets',
        sa.Column('id', sa.Integer, primary_key=True, autoincrement=False),
        sa.Column('first_name', sa.String(50), nullable=False),
        sa.Column('last_name', sa.String(50), nullable=False),
    )

    op.create_table(
        'specialties',
        sa.Column('id', sa.Integer, primary_key=True, autoincrement=False),
        sa.Column('name', sa.String(80), nullable=False),
    )

    op.create_table(
        'vet_specialties',
        sa.Column('vet_id', sa.Integer, sa.ForeignKey('vets.id'), primary_key=True),
        sa.Column('specialty_id', sa.Integer, sa.ForeignKey('specialties.id'), primary_key=True),
    )


def downgrade():
    op.drop_table('vet_specialties')
    op.drop_table('specialties')
    op.drop_table('vets')
"""create visits"""
from alembic import op
import sqlalchemy as sa

revision = '0003'
down_revision = '0002'
branch_labels = None
depends_on = None


def upgrade():
    op.create_table(
        'visits',
        sa.Column('id', sa.Integer, primary_key=True, autoincrement=False),
        sa.Column('pet_id', sa.Integer, sa.ForeignKey('pets.id'), nullable=False),
        sa.Column('visit_date', sa.Date, nullable=True),
        sa.Column('description', sa.String(255), nullable=True),
    )


def downgrade():
    op.drop_table('visits')
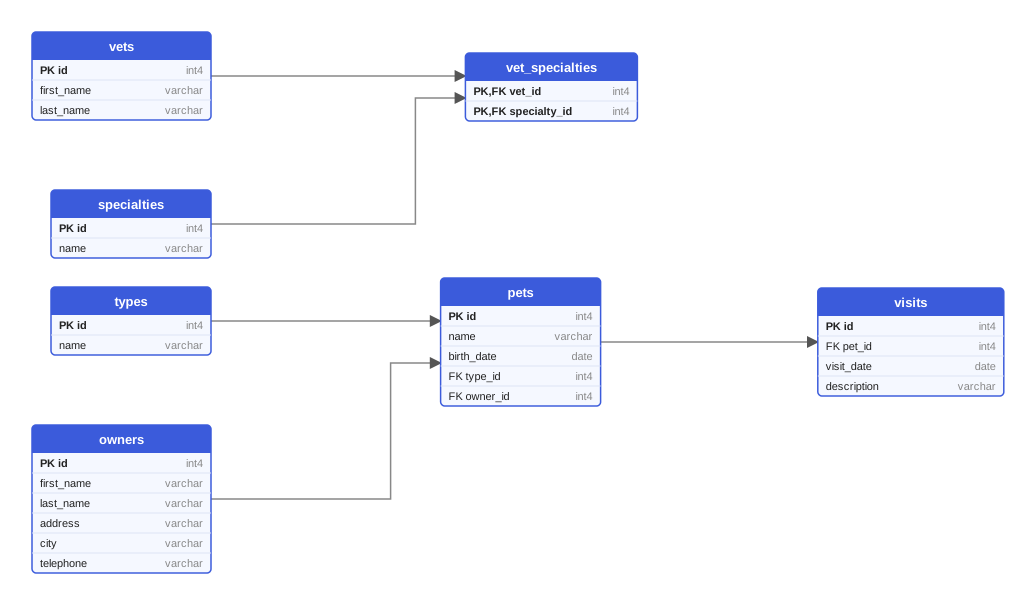
Every variant of the sample produces these seven tables. This diagram was drawn from the Flyway variant on PostgreSQL 18; on MySQL the types read INT and VARCHAR, on Oracle the names are upper case.
One multipart request queues the drawing; poll the job until it succeeds and download the SVG. Or let the GitHub Action do it and open a pull request with the diagram.
curl -X POST https://schemadrawer.com/api/v1/drawing \
  -H "Request-Id: $(uuidgen)" \
  -F "userId=5f0c1d2e-3a4b-4c5d-8e6f-7a8b9c0d1e2f" \
  -F "migrationType=ALEMBIC" \
  -F "databaseType=POSTGRESQL" \
  -F "version=18" \
  -F "files=@alembic/versions/0001_create_owners_and_pets.py" \
  -F "files=@alembic/versions/0002_create_vets.py" \
  -F "files=@alembic/versions/0003_create_visits.py"
# {"jobId":"0b6e2f4c-8d1a-4c3e-9f7a-2a5b6c7d8e9f"}
Then poll GET https://schemadrawer.com/api/v1/drawing/{jobId} until status is SUCCESS and fetch diagramUrl. Details in the getting started guide and the API reference.
- uses: schemadrawercom/action@v1
  with:
    sql-directory: alembic/versions
    output-path: docs/schema-diagram.svg
    migration-type: ALEMBIC
    database-type: POSTGRESQL
    database-version: '18'
    github-token: ${{ secrets.GITHUB_TOKEN }}
The action uploads the directory, waits for the diagram and opens a pull request with the SVG. See the action reference.
env.py and alembic.ini are not used. A revision script can import Alembic, SQLAlchemy and the drivers, but not your project's modules.alembic_version table is left out of the diagram.How Alembic autogenerate compares SQLAlchemy metadata with the live database, the changes it cannot see, constraint naming conventions and SQLite batch mode.
Editing applied migrations, environment-specific scripts, ORM auto-DDL in production, untested rollbacks: ten habits that break deployments, with a fix for each.
How Diesel manages a schema in Rust: the CLI, timestamped folders with up.sql and down.sql, the versions table, the generated schema.rs and embedded migrations.
Upload the migration directory, get an SVG back. Free while we build it.